
Quick and essential 'R' tricks for better, cleaner, more reproducible scripts.

quickcode is a collection of small, dependable helpers for everyday R scripting: a full family of not.* validation functions, PHP-style array/data-frame operations (push, pop, shuffle, rep), nullish-coalescing and "not in" operators, outlier and distribution detection, super variables, function-usage tracking, RStudio snippet addins, and more. None of it is flashy — it just removes boilerplate you'd otherwise rewrite in every project.
Install the released version from CRAN:
install.packages("quickcode")
Or install the development version from GitHub:
# install.packages("devtools")
devtools::install_github("oobianom/quickcode")
Load it like any other package:
library(quickcode)
is.null() has no built-in opposite. quickcode adds not.null(), not.na(), not.numeric(), not.integer(), not.logical(), not.vector(), not.data(), not.environment(), not.duplicated(), not.image(), not.inherits(), not.exists() and friends, so conditionals read the way you'd say them out loud.vector_push(), vector_pop(), data_push(), data_pop(), list_push(), data_shuffle(), data_rep() bring the array functions many scripters miss from other languages, working across vectors, lists, and data frames.%nin% (not in), %or% (nullish coalescing), %eo% (error coalescing), and %match% (string similarity) shorten common conditional patterns.refresh() / clean() clear the console, clear the environment, reset the working directory, and reload files/libraries in a single call.is.normal, is.poisson, is.weibull, ...), geometric mean/SD/CV, and histogram comparisons.newSuperVar() creates a variable that is accessible and mutable from any scope, with optional locking, class enforcement, and a limited number of permitted edits.track_func() wraps functions to record call frequency, timing, and argument patterns, for lightweight profiling and usage analytics.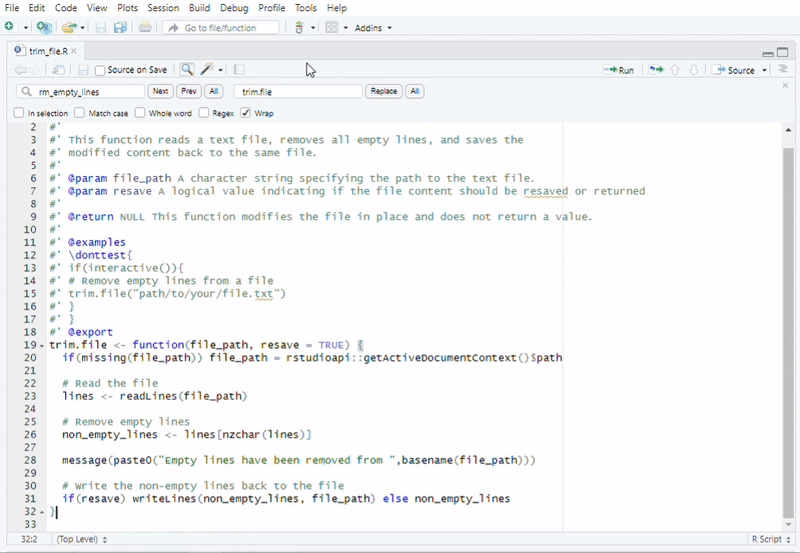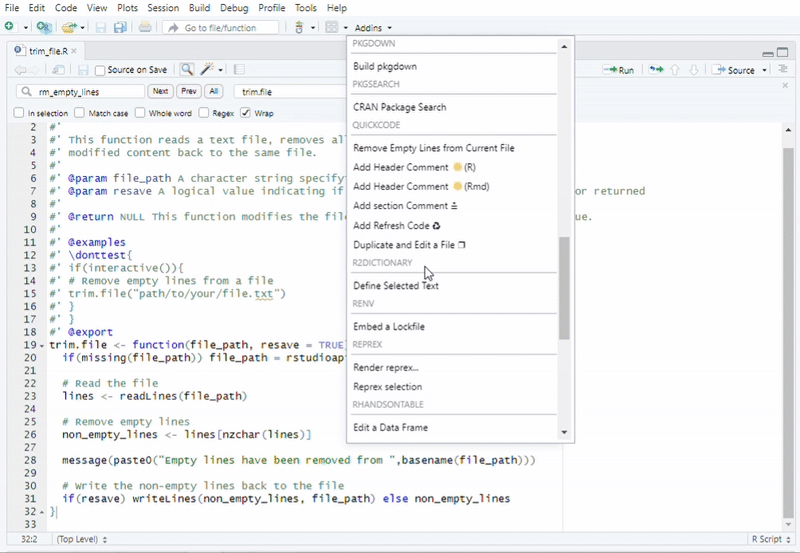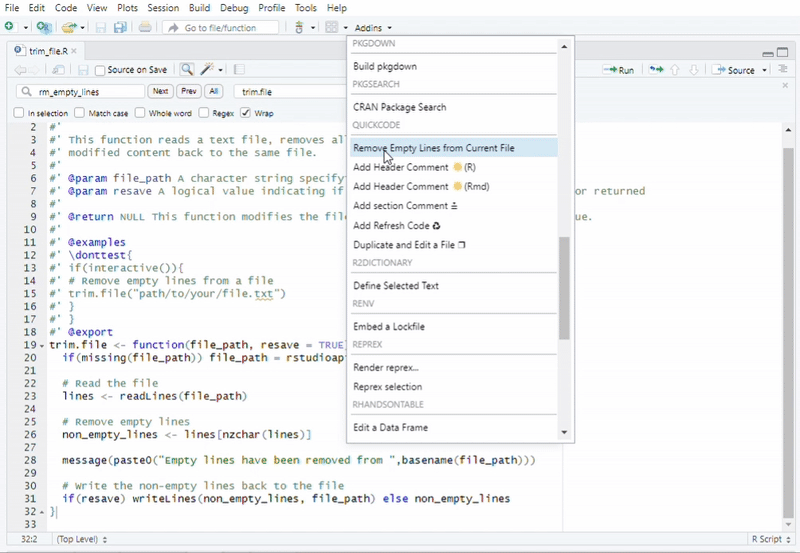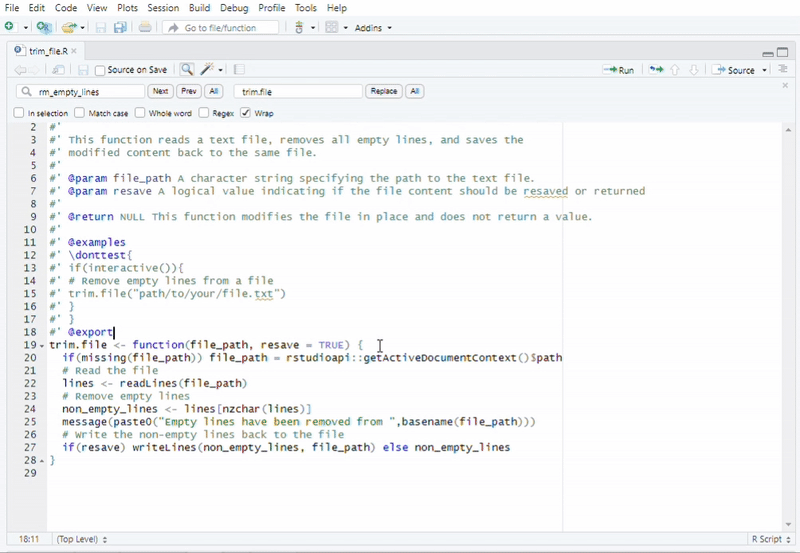
The not.* family
not.null(NULL)      # TRUE
not.na(NA)           # FALSE
not.integer(45L)     # FALSE
not.integer(45)      # TRUE
Nullish coalescing and "not in"
NULL %or% "default"        # "default"
NA %or% "default"          # "default"
5 %or% "default"           # 5

5 %nin% c(1:10)            # FALSE
5 %nin% c(11:20)           # TRUE
PHP-style vector and data frame helpers
p1 <- c(6, 7, 8)
p2 <- c(1, 2, 3)
vector_push(p1, p2)
p1
#> [1] 6 7 8 1 2 3

df1 <- data.frame(ID = 1:10, ID2 = 1:10)
df2 <- data.frame(ID = 11:20, ID2 = 21:30)
data_push(df1, df2, "rows")
One-line variable initialization
init(a, b, c)               # a, b, c set to NULL
init(x, y, z, value = 5)    # x, y, z set to 5
Environment reset
quickcode::refresh()

quickcode::clean(
  setwd  = "/path/to/project",
  source = c("file1.R", "file2.R"),
  load   = c("data.RData")
)
Super variables
newSuperVar(config, value = list(threshold = 10), lock = TRUE)
config                 # view current value
config.set(list(threshold = 20))  # blocked while locked
Outlier and distribution checks
x <- c(rnorm(100), 50)
detect_outlier2(x)
zscore(x)
is.normal(rnorm(100))
See vignette("quickcode_r_introduction") for a longer walkthrough.
| Function | Description |
|---|---|
not.null |
Not NULL |
not.na |
Not NA |
not.empty / is.empty
|
Not empty / is empty |
not.numeric |
Not numeric |
not.integer |
Not an integer |
not.logical |
Not logical |
not.vector |
Not a vector |
not.data |
Not a data object |
not.duplicated |
Not duplicated elements |
not.environment |
Not an environment |
not.image / is.image
|
File extension is/isn't an image |
not.inherits |
Does not inherit from specified classes |
not.exists |
Object does not exist |
has.error |
Check if a call or expression produces an error |
| Operator | Description |
|---|---|
%nin% (alias %!in%) |
Not in vector or array |
%or% |
Nullish coalescing operator |
%eo% |
Error coalescing operator |
%match% |
Percentage string similarity match |
%.% |
Simple function chaining |
| Function | Description |
|---|---|
vector_push / vector_pop
|
Add / remove elements from a vector |
list_push |
Add elements to a list |
data_push / data_pop
|
Add / remove rows or columns from a data frame |
data_pop_filter |
Remove elements from data matching a filter |
data_rep / rows.rep / cols.rep
|
Duplicate rows or columns X times |
data_shuffle / list_shuffle / vector_shuffle
|
Shuffle a data frame, list, or vector |
switch_rows / switch_cols
|
Swap two rows or columns |
sample_by_column |
Re-sample a dataset by column |
mutate_filter |
Mutate only a subset of a dataset |
add_key (alias indexed) |
Add index keys to a vector, list, data frame, or matrix |
| Function | Description |
|---|---|
init |
Initialize one or more variables/objects at once |
newSuperVar |
Create a variable accessible/mutable from any scope, with locking and edit limits |
setOnce |
Set a variable only once |
refresh / clean / libraryAll
|
Clear environment/console, reset working directory, load files & libraries |
summarize.envobj |
Summarize environment objects and their sizes |
lastwd |
Return to the previous working directory |
| Function | Description |
|---|---|
zscore / zscore_outlier / zscore_outlier2
|
Z-score calculation and z-score-based outlier flagging |
detect_outlier / detect_outlier2 / iqr_outlier
|
Outlier detection (including grouped) |
is.normal, is.lognormal, is.uniform, is.poisson, is.gamma, is.weibull, is.cauchy, is.logistic
|
Test whether data fits a given distribution |
getDistribution |
Fit-check data against a distribution |
geo.mean, geo.sd, geo.cv
|
Geometric mean, standard deviation, coefficient of variation |
mode.calc |
Mode of a numeric or character vector |
na.cumsum |
Cumulative sum with NA removal |
normalize.vector |
Normalize a numeric vector to [0, 1] |
sub.range / in.range
|
Range difference / range membership checks |
unique_len |
Combine unique() and length()
|
pairDist |
Distance of points from a cluster center |
compHist |
Compare histograms of two distributions |
| Function | Description |
|---|---|
cat_to_num / cat_to_num2
|
Convert categorical values to numeric |
from_tensor_slices |
Create tensor-like slices from a data frame or matrix |
multihead_att |
Multi-head attention computation |
learn_rate_scheduler |
Learning rate scheduling utilities |
make_dosing_df |
Create subject-by-time dosing records with covariates |
| Function | Description |
|---|---|
bionic_txt |
Generate bionic-reading formatted text |
randString |
Generate a random string |
strsplit.bool / strsplit.num
|
Split a string into a boolean / numeric vector |
percent_match |
Percentage match between two strings |
ndecimal |
Count decimal places in a number |
as.boolean / yesNoBool
|
Convert between boolean representations |
extract_comment / remove_comment / remove_content_in_quotes
|
Text/comment extraction and cleanup |
getDate |
Extract all dates from a string |
extract_IP |
Extract IP addresses from a string |
| Function | Description |
|---|---|
date1to3 / date3to1
|
Combine vectors into a Date, or split a Date into vectors |
getWeekSeq |
Convert dates into numeric week counts |
is.leap |
Check whether a year is a leap year |
fAddDate |
Append a date to a filename |
is.increasing / is.decreasing
|
Check whether values in a vector are increasing/decreasing |
| Function | Description |
|---|---|
duplicate |
Duplicate a file with global text replacement |
ai.duplicate |
Prompt-guided duplication and editing of files |
trim.file |
Remove empty lines from a file |
sort_file_type / sort_length
|
Sort a vector by file type or content length |
read.csv.print / read.table.print
|
Read and preview the first X rows/columns of a file |
insertInText |
Insert a string into the current RStudio file (Shiny helper) |
| Addin / function | Description |
|---|---|
add.header |
Add a header comment to the current R file |
header.rmd |
Add a header comment to the current Rmd file |
add.sect.comment |
Insert a custom section comment |
add.snippet.clear |
Insert a console-clear / set-directory snippet |
| Function | Description |
|---|---|
rcolorconst |
Named R color constants |
mix.color / mix.cols.btw
|
Blend two or more colors |
setDisAlpha / unsetDisAlpha
|
Set/unset color transparency |
create_shape |
Create geometric shapes with optional text |
| Function | Description |
|---|---|
find_packages |
Search CRAN packages by keyword |
archivedPkg |
List all CRAN-archived R packages |
rDecomPkg |
Check whether a package has been decommissioned from CRAN |
getGitRepoStart / getGitRepoChange
|
Fetch a GitHub repo's creation / last-updated date |
track_func |
Track function call frequency, timing, and usage patterns |
| Function | Description |
|---|---|
plus / minus / inc
|
Increment or decrement a vector by a value |
number |
Generate random integers |
const |
Common mathematical constants |
math.mm / math.qt
|
Miscellaneous math and confidence-interval computations |
error.out (%eo%) |
Return an alternative value if an expression errors |
or (%or%) |
Return an alternative value if an expression is empty/NA/NULL |
chain_sep (%.%) / chain_func
|
Simple function chaining |
This list covers the most commonly used functions; run library(help = "quickcode") or browse the man/ directory for the complete, authoritative reference with full argument details and runnable examples.
vignette("quickcode_r_introduction") — general tour of the packagevignette("add_today_date_to_filenames_quickcode") — appending dates to filenames with fAddDate()
vignette("nullish_coalescing_operator_r") — using %or% and %eo%
vignette("track_function_usage_r") — profiling function usage with track_func()
MIT © Obinna Obianom. See LICENSE for details.